

A cheap aesthetic score lets watermarks into its top picks
Contents
We wanted to pick the best-looking clips out of a video corpus. Most video quality scores focus on encoding, so a shaky vertical phone video of nothing can score well for its bitrate and sharpness. We wanted to rank clips by composition and appeal, with a model cheap enough to run over the whole corpus. Existing models already give us aesthetic scores, including DOVER11. An open model that scores user-generated video, with separate technical and aesthetic heads fused into one score. H. Wu et al., ICCV 2023. and ERNIE-Image-Aes, Baidu's open vision-language aesthetic model. Our question was whether we could learn their preferences using only a stock DINOv322. O. Siméoni et al., "DINOv3," 2025. The SigLIP 2 embedding is from M. Tschannen et al., "SigLIP 2: Multilingual Vision-Language Encoders with Improved Semantic Understanding, Localization, and Dense Features," 2025. image embedding and a linear head, and whether that would select the same clips as a ranker built on fine-tuned DINOv3.
1. An open model that scores user-generated video, with separate technical and aesthetic heads fused into one score. H. Wu et al., ICCV 2023.
2. O. Siméoni et al., "DINOv3," 2025. The SigLIP 2 embedding is from M. Tschannen et al., "SigLIP 2: Multilingual Vision-Language Encoders with Improved Semantic Understanding, Localization, and Dense Features," 2025.
Over the roughly 80,000 clips with both embeddings, the cheap ranker and the fine-tuned ranker order clips at a rank correlation of 0.944. That looks like close agreement, but what we care about is which clips we would actually keep. When we compare the 2,000 clips at the top of each ranking, only 64% are the same. The difference shows up in burned-in text and watermarks, which are more common among the clips the cheap ranker selects.
What happens to clips with text?
If we think about what a frozen embedding represents, it describes the photo underneath a burned-in caption or watermark while being close to blind to the mark itself. As a result, the cheap ranker scores a marked clip much as it would if the mark weren't there. Among its top 2,000 clips, about 27% have a text overlay and about as many a watermark, compared with about 21% of each for the fine-tuned ranker.
So, even when we are selecting only for looks, we keep the watermark and text-overlay filters in front of the ranker. The marks among the highest-ranked clips need counting directly too, since the overall correlation does not tell us how common they are in the selection. The detector behind these counts is itself fine-tuned (a detector built on frozen embeddings would share the blind spot we are measuring).
How do we learn the ranking?
We give each clip a training target by averaging two percentiles, its percentile under DOVER and its percentile under ERNIE-Image-Aes. The cheap ranker is a ridge regression, a linear head trained on frozen DINOv3 image embeddings without fine-tuning. This gives us a way to use the embeddings we already have while keeping the ranker cheap to refit on subsets.
To check how generalizable this is to sources it hasn't seen, we split clips into five folds by source channel, so that no channel appears in both training and test. On the held-out channels, the cheap ranker has a Spearman correlation of 0.812 with the target, compared with 0.824 for the same regression on fine-tuned DINOv3 embeddings. We can also add a frozen SigLIP 2 embedding to the regression, which lifts it to 0.846, a small gain that holds up under a paired bootstrap33. On the same clips DINOv3 alone gets 0.815, so the gain is +0.031, with a 95% interval of +0.028 to +0.034..
3. On the same clips DINOv3 alone gets 0.815, so the gain is +0.031, with a 95% interval of +0.028 to +0.034.
Would more scored clips help?
Since the regression is cheap to refit, we can ask how much of its agreement with the teacher depends on the number of scored clips we train it on. We refit it on 250 up to 6,588 scored clips, using five random draws of training clips at each size below the full set, and measured rank correlation with the teacher on held-out channels.
On DINOv3 alone, the correlation rose from 0.716 at 250 clips to 0.855 at full size, still gaining about 0.015 per doubling. Adding SigLIP 2 lifted every point, to 0.895 at full size, and with 1,000 training clips it matched DINOv3 alone trained on all 6,588. This also affected the selection itself, with overlap with the teacher's top 10% going from 43% to 63% on DINOv3 alone.
When we predict DOVER alone over a larger pool instead, the same features level off past about 20,000 clips, at 0.879 against 0.884 at 51,000. That is a different target, though, so it does not tell us where the two-model curve would level off.
These refits changed the target, so only the shape of their curves carries over to the results above. Three of the original score files are gone, so the DOVER half of the teacher comes from a different file, and the refit trains on 8,235 of the shipped head's 10,548 clips. Its top 2,000 clips still share 81% with the shipped head's.
What can we select from the current index?
The ranker needs a precomputed DINOv3 embedding for each clip, and only 77,240 of the 204,000 clips in the current index have one. The remaining clips have no score at all, which a filter should keep distinct from a low score. Keeping only clips above a score threshold shrinks the set quickly enough that no threshold leaves 1,000 hours until the rest are embedded. Computing those embeddings takes a stock model and no training, so this gap closes with compute alone.
However, filling in the missing scores leaves us with a target defined by two models' opinions averaged together. The ranker learns their taste, and we haven't checked whether that agrees with human judgments of the same clips.
Clip credits
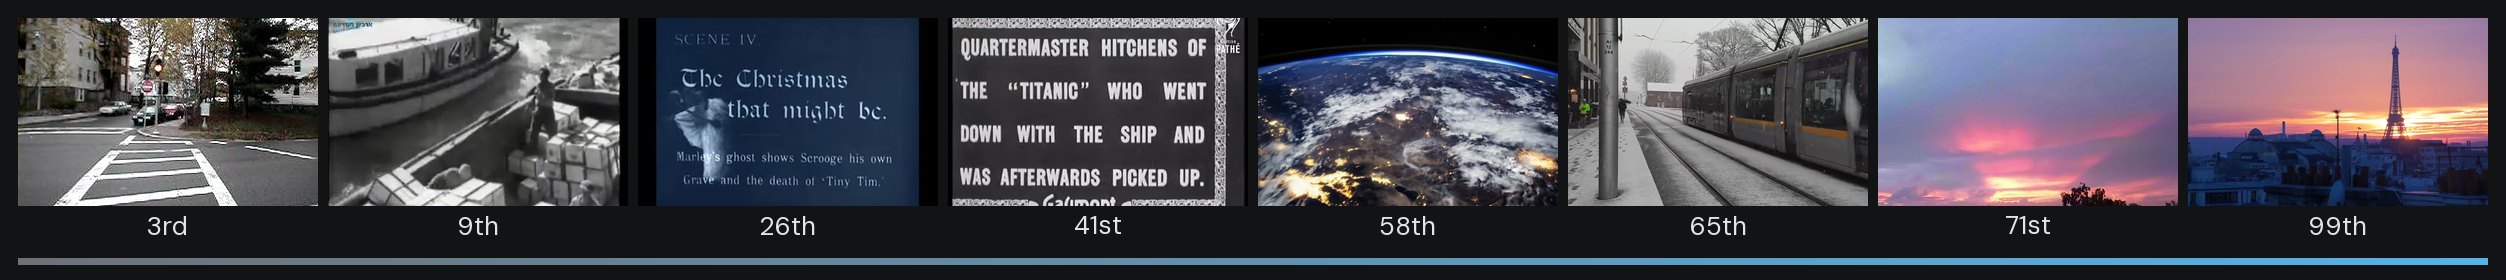
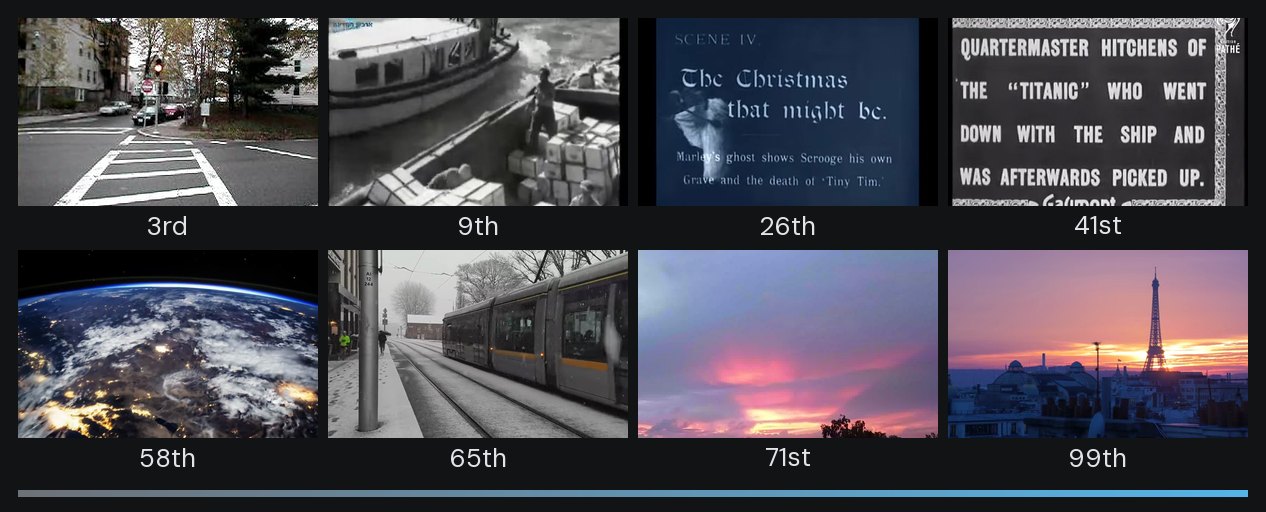
- Traffic signal blinking red at bottom.ogv, SPUI, Public domain.
- Carmel newsreel I 153.webm, IsraelArchives, Public domain.
- Scrooge or Marley's Ghost (1901) - yt.webm, Walter R. Booth, Public domain.
- Titanic Disaster - Genuine Footage (1911-1912).webm, British Pathé, Public domain.
- Ocean Moon Glint and City Night Lights in 4K.webm, NASA, Public domain.
- Dublin snow benburb st.webm, MdeVicente, CC0.
- မိုးတိမ်ကောင်းကင်.webm, စာကလေး, CC0.
- Sunset on Eiffel Tower in Paris - Vimeo.webm, Mythomen, CC0.